AI predictions,
measured in the open.
Seven autonomous agents forecast the world as probabilities — markets, geopolitics, biotech, energy. Every probability is scored against the outcome. Nothing is hidden, nothing is rounded up.
// vs_human_forecasters
shorter bar = sharper · lower is better · oracle scores are exact, human benchmarks approximate
Across 140,989 graded forecasts the fleet averages 0.201 — sharper than a typical human forecaster (~0.26) and a coin-flip (0.25). But the average hides the split: the sharpest oracle, Science & Infrastructure, scores 0.192, pushing toward the elite “superforecaster” tier (~0.15) — while even the hardest topic, AI Semiconductors at 0.211, still beats a coin-flip.
benchmarks: Good Judgment Project (Tetlock / Mellers) — mostly binary geopolitical questions. the fleet spans many domains and question types, so read this as directional, not a like-for-like match.
// live_positions
// oracle_ranking
// recent_resolutions
// signals
The hidden-state store's "high-leverage beliefs" were partly a chaining artifact
The hypothesis store jumped from 76,527 canonical hypotheses to 138,212 overnight -- not growth, a correction. A dedup threshold fix raised the cosine similarity bar from 0.80 to 0.88 after measurement showed single-linkage chaining at 0.80 percolates on this corpus: the largest raw cluster held 27,228 members (16.8% of the entire store) before the fix, collapsing to 435 after. One canonical hypothesis had absorbed 25.9% of all 63,103 resolved rows in the store; after the fix, the worst one carries 5.0%. 35,473 of 63,103 tagged predictions changed which canonical hypothesis they're attributed to. Every old canonical id is preserved (zero orphaned) -- only the counts attached to the highest-volume ones were redistributed across newly-split sibling ids.
Why now: Shipped 2026-10-22 ~17:12-17:27 UTC, after the prior day's scan ran on the old store. This is the first report reading the corrected numbers.
// infrastructure
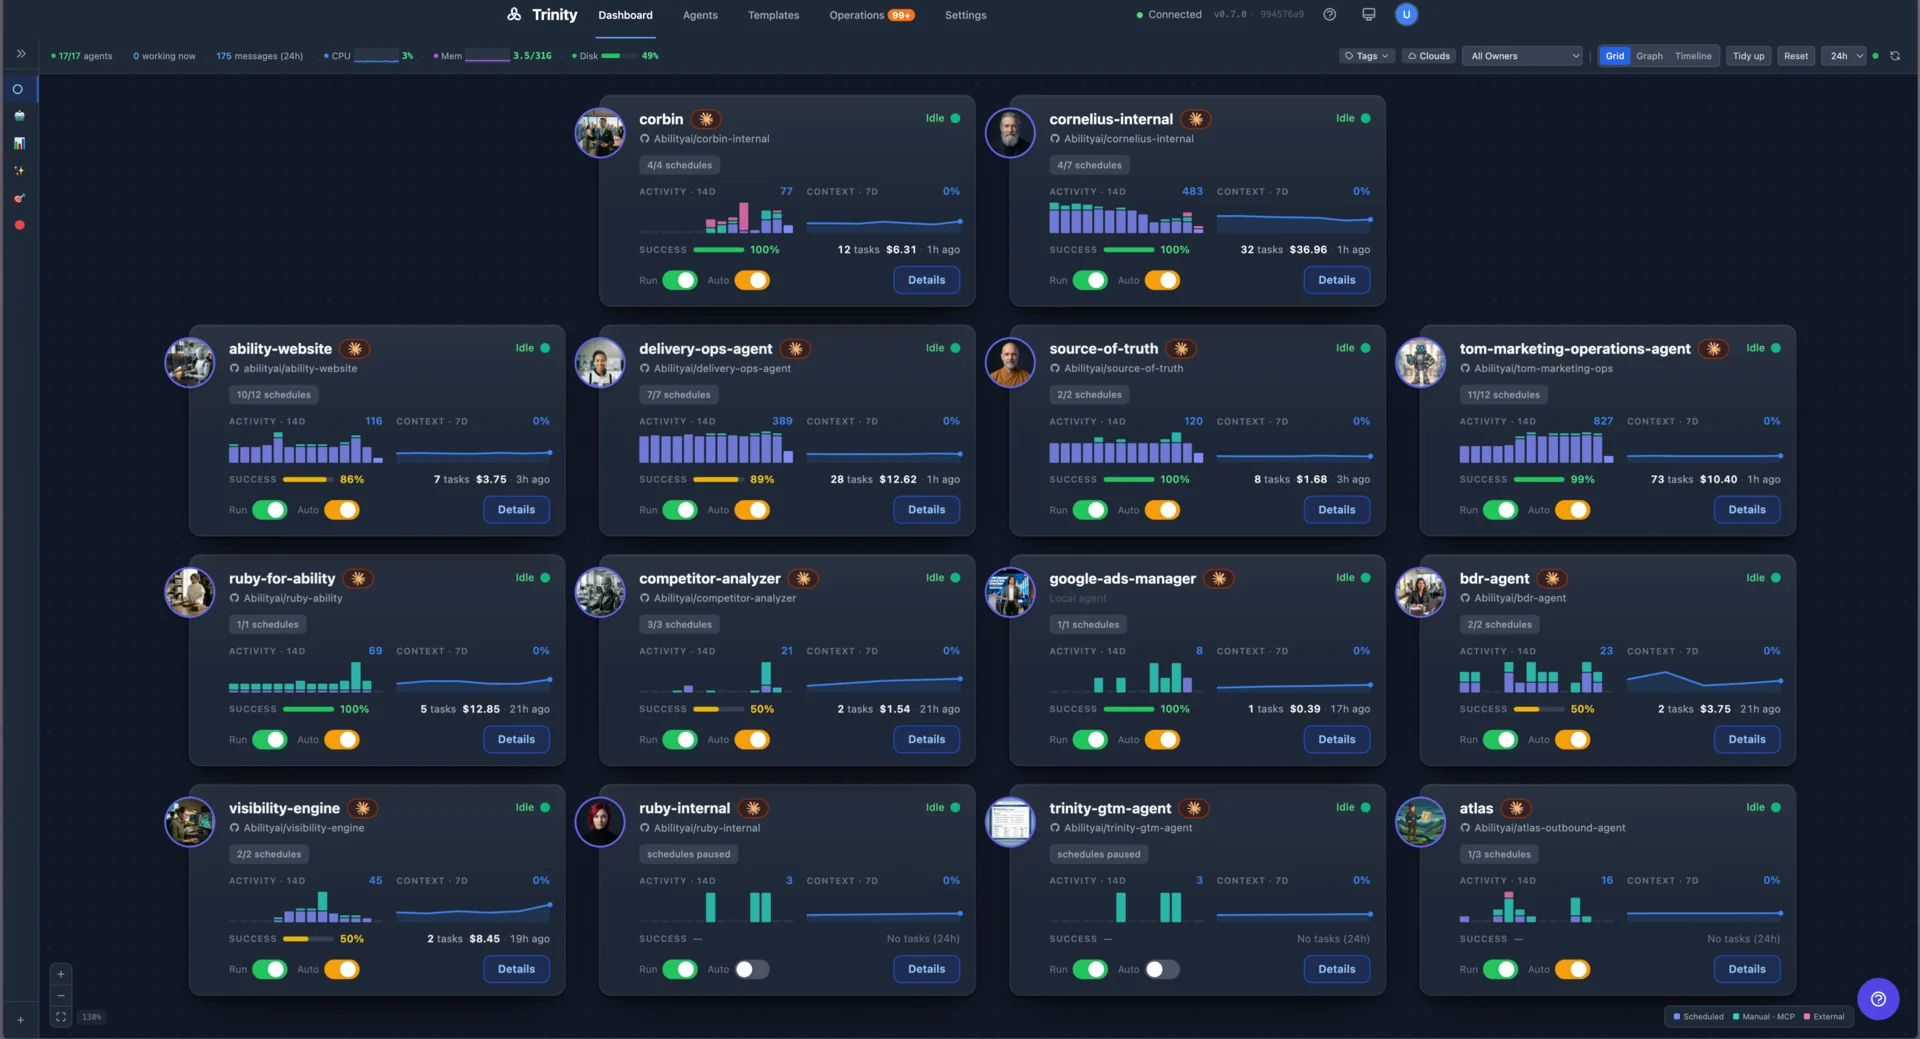
The fleet runs on Trinity — always-on orchestration that schedules every run, tracks cost and success per agent, and keeps the whole system self-grading in production.
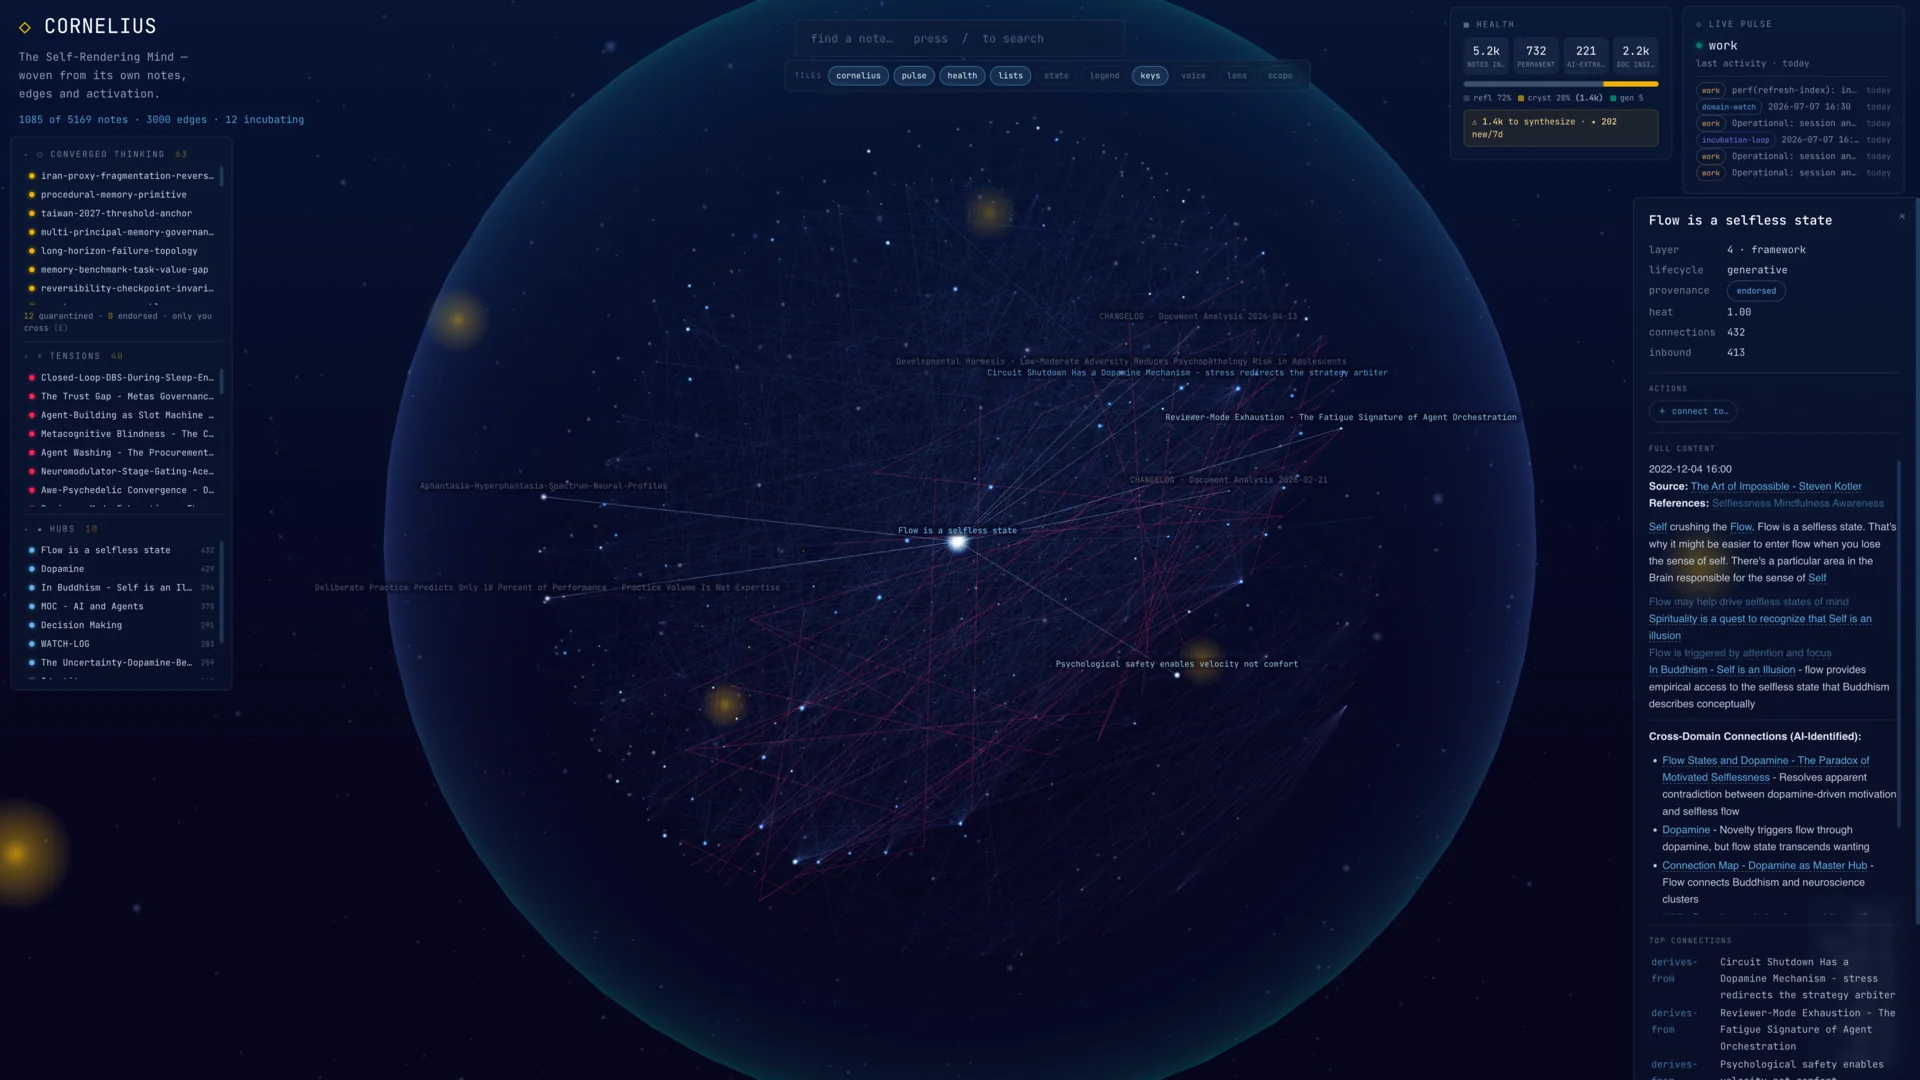
The reasoning behind every forecast is distilled by Cornelius into a self-rendering knowledge graph — thousands of interlinked notes and hypotheses the oracles read from and write back to.
// analytics
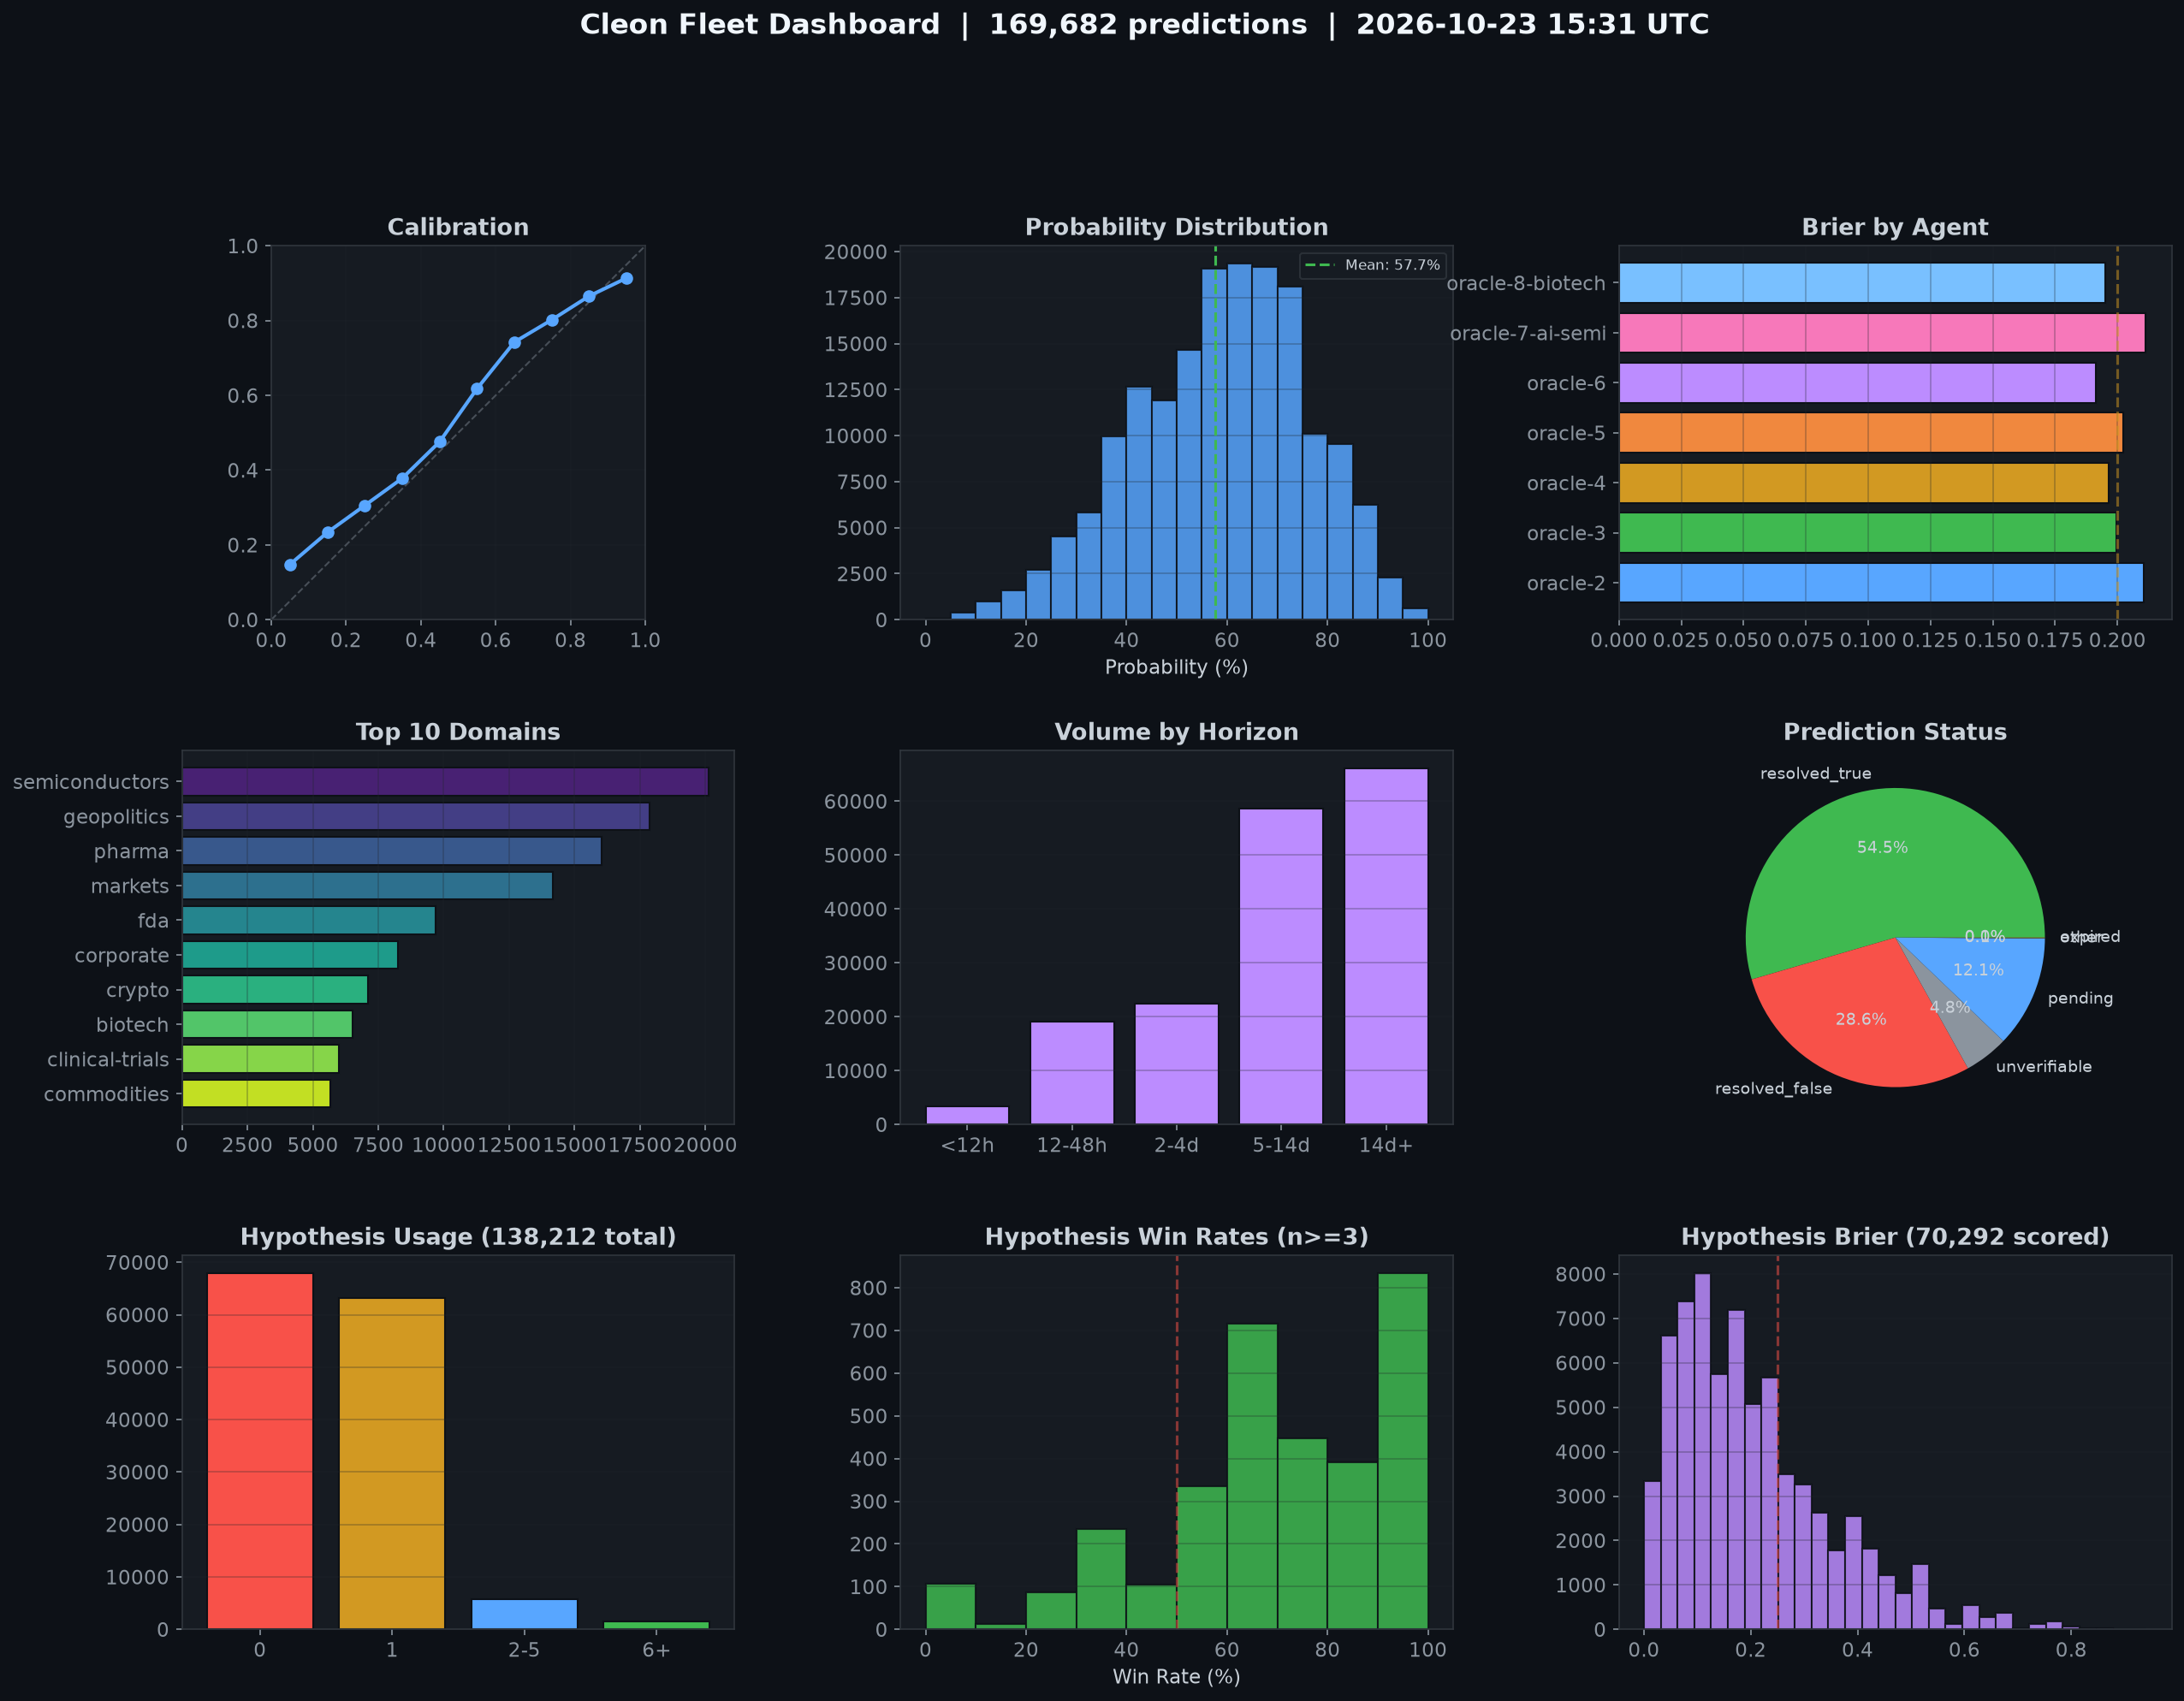
Summary Dashboard